How I Built an Infinite List That Does Not Grow Forever
How cursor pagination, a bounded query cache, and list virtualization keep an infinite list fast across hundreds of millions of records.
Browsing more than 300 million records sounds like a browser-crashing idea. I built a Next.js experiment that can keep scrolling while holding only 250 records in memory and rendering roughly 10–20 rows.
Stack: Next.js · TanStack Query · TanStack Virtual · OpenAlex API
Infinite scroll looks simple: fetch another page when the user reaches the bottom. The hidden problem is that a basic implementation keeps every fetched record in JavaScript memory and may also keep every row in the DOM. A long session therefore gets heavier with every swipe.
I wanted to test a different question:
Can the scrolling distance grow while the amount of work performed by the browser stays almost constant?
To make the test realistic, I used OpenAlex instead of generating fake rows. OpenAlex provides a huge catalog of scholarly works and supports cursor pagination for moving through large result sets.
The finished demo includes four live counters:
- Available: the total number of matching records on OpenAlex.
- Cached now: the records currently stored in browser memory.
- Rendered now: the rows that currently exist as DOM elements.
- Seen this run: every record loaded during the current scrolling session, including records that have already been removed from the cache.
Watching these counters change makes an otherwise invisible performance pattern much easier to understand.
The three different quantities
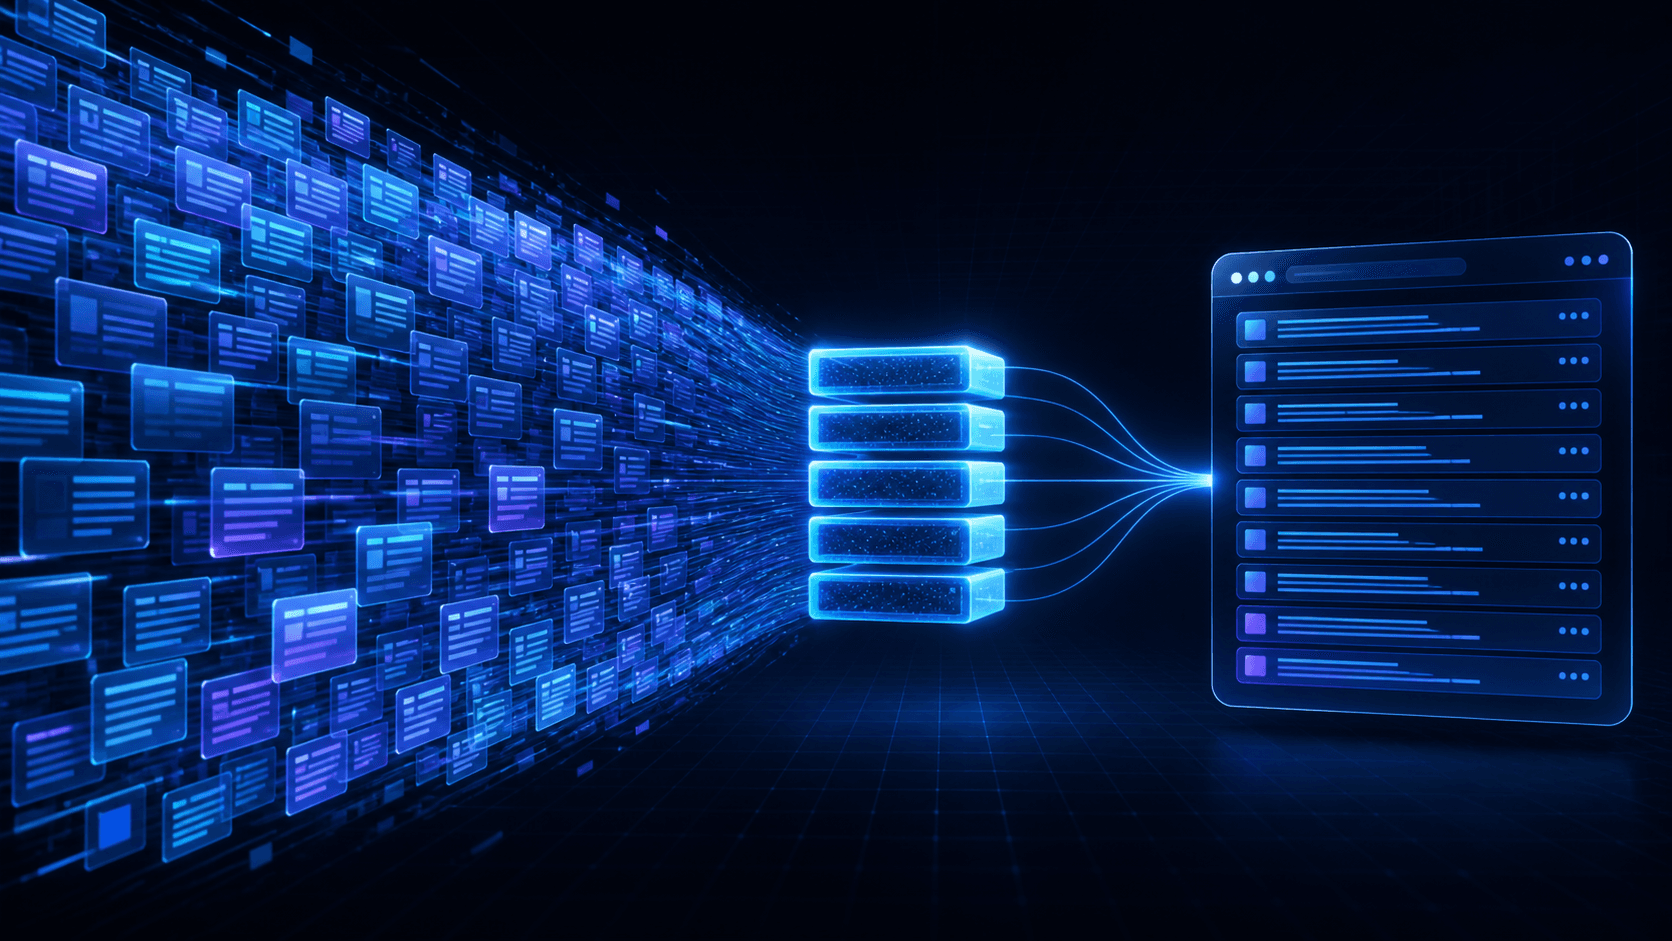
The central idea is to separate what exists on the server, what is cached in the browser, and what is currently drawn on screen.
| Layer | Approximate size | Meaning |
|---|---|---|
| OpenAlex | 300 million+ | Records available from the API |
TanStack Query cache | Maximum 250 | Records immediately available in JavaScript memory |
| Browser DOM | Roughly 10–20 | Rows the browser must currently lay out and paint |
“Cached” does not mean “rendered.” Cached records are ordinary JavaScript objects ready for the UI to use. Rendered rows are actual HTML elements that the browser must calculate, position, style, and paint.
Think of the cache as a small bookshelf beside your desk. The complete library still exists on the server, but only a few books are kept close enough to use immediately. The DOM is even smaller: it is like keeping only the pages currently open in front of you.
A record can therefore be:
- Available remotely.
- Loaded into the local cache.
- Rendered into the current viewport.
Each state has a different cost. Controlling both the cache and the DOM is what makes the experiment useful.
Each tool has one responsibility
It is easy to describe the project as one “infinite-scroll feature,” but four separate pieces cooperate to create it.
OpenAlex
OpenAlex owns the complete dataset. It sends 50 works at a time and provides a cursor that points to the next group.
Next.js route handler
The browser calls a local /api/openalex route. That route forwards the request to OpenAlex, keeps an optional API key on the server, and converts upstream failures into useful error messages.
TanStack Query
TanStack Query requests pages, stores successful responses, tracks loading and error states, and controls how many pages remain in memory.
TanStack Virtual
TanStack Virtual observes the scroll container and calculates which cached records are currently visible. Only those records become DOM elements.
This separation is important. TanStack Query does not know which rows are visible, and TanStack Virtual does not fetch data. Query manages server state; Virtual manages browser rendering. Together they solve two different growth problems.
Cursor pagination supplies the stream
OpenAlex cursor pagination starts with *. Each API response contains a next_cursor, which is passed into the following request.
initialPageParam: "*",

getNextPageParam: (lastPage) =>
  lastPage.meta.next_cursor ?? undefined
The application asks for 50 works at a time and requests only the fields displayed in the interface:
const params = new URLSearchParams({
  cursor,
  per_page: "50",
  select: "id,display_name,publication_year,cited_by_count,type",
});
Requesting fewer fields reduces response size and avoids transferring data that the interface never uses.
Why use a cursor instead of a page number?
A page number effectively says, “skip a certain number of rows and give me the next group.” Deep offsets can become inefficient, and a changing dataset can cause records to move between pages.
A cursor is an opaque bookmark created by the API. The client does not need to understand its contents. It only returns the bookmark to request the next slice. This is a natural fit for a feed that moves forward sequentially.
The data flow looks like this:
Browser
   ↓  /api/openalex?cursor=...
Next.js route
   ↓  secure server-side request
OpenAlex
   ↓  50 works + next_cursor
TanStack Query cache
A cache with a hard ceiling
useInfiniteQuery stores API responses as an array of pages:
data.pages = [page1, page2, page3, page4, page5]
Without a limit, every new page would remain in that array. After a long scrolling session, the browser might contain thousands of records that the user can no longer see.
The important configuration is maxPages:
useInfiniteQuery({
  queryKey: ["openalex-works"],
  queryFn: getWorks,
  initialPageParam: "*",
  getNextPageParam: (lastPage) => lastPage.meta.next_cursor ?? undefined,
  maxPages: 5,
});
One page contains 50 records, and the cache keeps five pages:
50 records × 5 pages = 250 cached records
When page six arrives, page one is removed:
Before:
[Page 1] [Page 2] [Page 3] [Page 4] [Page 5]

Fetch Page 6
                     ↓

After:
[Page 2] [Page 3] [Page 4] [Page 5] [Page 6]
The result is a sliding window over the dataset. A user could reach record 10,000 without forcing the browser to remember the previous 9,750 records.
The subtle scroll-position bug
Removing an old page creates a UI problem.
Each row in the demo is 96 pixels tall. Removing a page of 50 rows removes 4,800 pixels above the current viewport:
50 rows × 96 pixels = 4,800 pixels
If nothing else changes, the visible content jumps because the scroll position still refers to the old virtual height. The solution is to subtract the removed height from scrollTop at the same moment the oldest page is evicted.
const removedHeight = firstPageSize * ROW_HEIGHT;

parentRef.current.scrollTop = Math.max(
  0,
  parentRef.current.scrollTop - removedHeight
);
The user remains anchored to the same scholarly work while the old page disappears behind the viewport. This correction is small, but it is the difference between a convincing infinite list and a list that appears broken after the cache reaches its limit.
It also prevents another problem: if the viewport remained stuck at the bottom after every eviction, the bottom detector could immediately request another page without waiting for the user to scroll again.
Virtualization controls the DOM
Limiting the query cache solves only half of the problem. Rendering all 250 cached rows is still unnecessary when the user can see only six or seven at once.
TanStack Virtual receives four important values:
const virtualizer = useVirtualizer({
  count: works.length,
  getScrollElement: () => parentRef.current,
  estimateSize: () => 96,
  overscan: 5,
});
counttells it how many cached records exist.getScrollElementidentifies the element being scrolled.estimateSizedescribes the expected row height.overscanadds a small buffer above and below the viewport.
The virtualizer creates the measurements for a tall invisible canvas. The application then renders only the rows returned by getVirtualItems():
const virtualItems = virtualizer.getVirtualItems();

return virtualItems.map((virtualRow) => (
  <article
    key={works[virtualRow.index].id}
    style={{
      height: `${ROW_HEIGHT}px`,
      transform: `translateY(${virtualRow.start}px)`,
    }}
  >
    {/* Visible row content */}
  </article>
));
Rows outside that range are not hidden with CSS. They do not exist in the DOM at all.
Why include overscan?
Rendering exactly the visible rows sounds optimal, but it can briefly reveal empty space during a fast scroll. An overscan value of five renders a few extra rows immediately above and below the viewport.
That tiny amount of additional work gives the browser a buffer and makes movement feel smoother. It is a practical tradeoff: slightly more DOM work in exchange for fewer visible rendering gaps.
Detecting when to load more
The list requests another page when the last virtual row is within eight records of the current cached end:
useEffect(() => {
  const lastItem = virtualItems.at(-1);
  if (!lastItem || works.length === 0) return;

  const isNearEnd = lastItem.index >= works.length - 8;

  if (isNearEnd && hasNextPage && !isFetchingNextPage) {
    void fetchNextPage();
  }
}, [
  fetchNextPage,
  hasNextPage,
  isFetchingNextPage,
  virtualItems,
  works.length,
]);
Loading a little before the exact end helps the next records arrive before the user sees an empty gap.
The two boolean checks are important:
hasNextPageprevents requests after the API reaches the end.isFetchingNextPageprevents duplicate requests while a request is already running.
What happens during one scroll
Imagine that five pages are already cached and the user approaches the bottom:
- TanStack Virtual detects the visible range. The last visible row is close to the end of the cached records.
- The loading effect requests another page. TanStack Query passes the latest cursor to the fetch function.
- OpenAlex returns 50 more works. The response also includes a cursor for the following request.
- TanStack Query inserts the new page. Because the cache is full, it removes the oldest page at the same time.
- The application corrects the scroll offset. The viewport remains anchored to the same work after the old rows disappear.
- TanStack Virtual recalculates the visible rows. Rows leaving the viewport are removed from the DOM and new rows take their place.
This cycle can repeat as long as OpenAlex returns another cursor. The record numbers increase, while the cache and DOM sizes settle around their configured limits.
What the browser test proved
I tested the implementation using real OpenAlex responses rather than relying only on code inspection.
During the test, I scrolled through 400 records. At that point, the interface reported:
Records seen:       400
Records evicted:    150
Records cached:     250
DOM rows rendered:   17
The numbers match the intended architecture:
- Network usage grows only when the user requests more data.
- Query memory stops growing after five pages.
- DOM size follows the viewport rather than the dataset.
- The current row remains visually stable when old data is removed.
This does not mean the browser performs zero work. New requests still consume bandwidth, responses must still be parsed, and scrolling still causes rendering updates. The important result is that the amount of retained work no longer grows with the entire scrolling history.
The tradeoff
A bounded forward-only list intentionally forgets old pages. That is ideal for feeds where the primary action is continuing downward.
If the product must support unlimited scrolling in both directions, it also needs previous-page cursors, scroll restoration, or persisted data outside the query cache. TanStack Query supports previous-page fetching, but the application must decide when to retrieve evicted content and how to keep the viewport stable while prepending it.
This pattern is a strong fit for:
- Discovery feeds.
- Activity and audit logs.
- Search results.
- Large analytics tables.
- News and social timelines.
- Catalog browsing.
It is less suitable when every loaded item must remain instantly editable, selectable, or searchable on the client. In those cases, removing older data from memory may conflict with the product requirements.
Performance is not free. In this design, it comes from making an explicit decision about what the interface is allowed to forget.
What I would add for production
This experiment focuses on the central performance pattern. A production implementation would add safeguards based on the needs of the product:
- Exponential backoff and clearer messaging for API rate limits.
- Previous-page fetching when users must scroll back through evicted data.
- Scroll restoration after visiting a detail page and returning.
- Accessible keyboard navigation and focus management for interactive rows.
- A non-JavaScript fallback or standard pagination where appropriate.
- Monitoring for request latency, failed pages, memory usage, and scroll performance.
- Automated tests for page eviction and scroll anchoring.
The important lesson is not that every infinite list needs every feature above. It is that cache size, rendering strategy, navigation behavior, and accessibility should be designed together instead of being added independently after performance problems appear.
Final takeaway
Infinite scrolling is not just about loading more records. A reliable implementation must answer three separate questions:
- How is the next group of data requested? Cursor pagination.
- How much fetched data remains in memory? A bounded query cache.
- How much cached data becomes HTML? List virtualization.
Together, OpenAlex, TanStack Query, and TanStack Virtual create a list that can travel through an enormous dataset while keeping browser resource usage predictable.
The dataset may contain hundreds of millions of records. The browser does not need to hold hundreds of millions—or even thousands—to make that journey feel continuous.